
Revolutionizing AI: How Prism ML's Tiny LLMs Could Reshape Our Interaction with AI [2025]
Prism ML, a pioneering AI lab, is making waves with its groundbreaking approach to large language models (LLMs). By dramatically reducing the size of these models, Prism ML is challenging the status quo and opening new possibilities for AI applications on everyday devices. This article delves into the mechanics of Prism ML's innovations, explores their implications, and provides practical insights for developers and businesses looking to leverage these advancements.
TL; DR
- Prism ML's innovation: Shrinks LLMs like the Qwen 3.8 27B to just 5.9 GB, enabling deployment on PCs and smartphones.
- Technical breakthrough: Achieved through advanced compression techniques, drastically lowering memory requirements.
- Practical applications: Enhances AI accessibility, enabling real-time processing on personal devices without cloud dependency.
- Developer insights: Guidelines for implementing tiny LLMs in various sectors.
- Future trends: Anticipated shifts in AI usage and potential industry impacts.
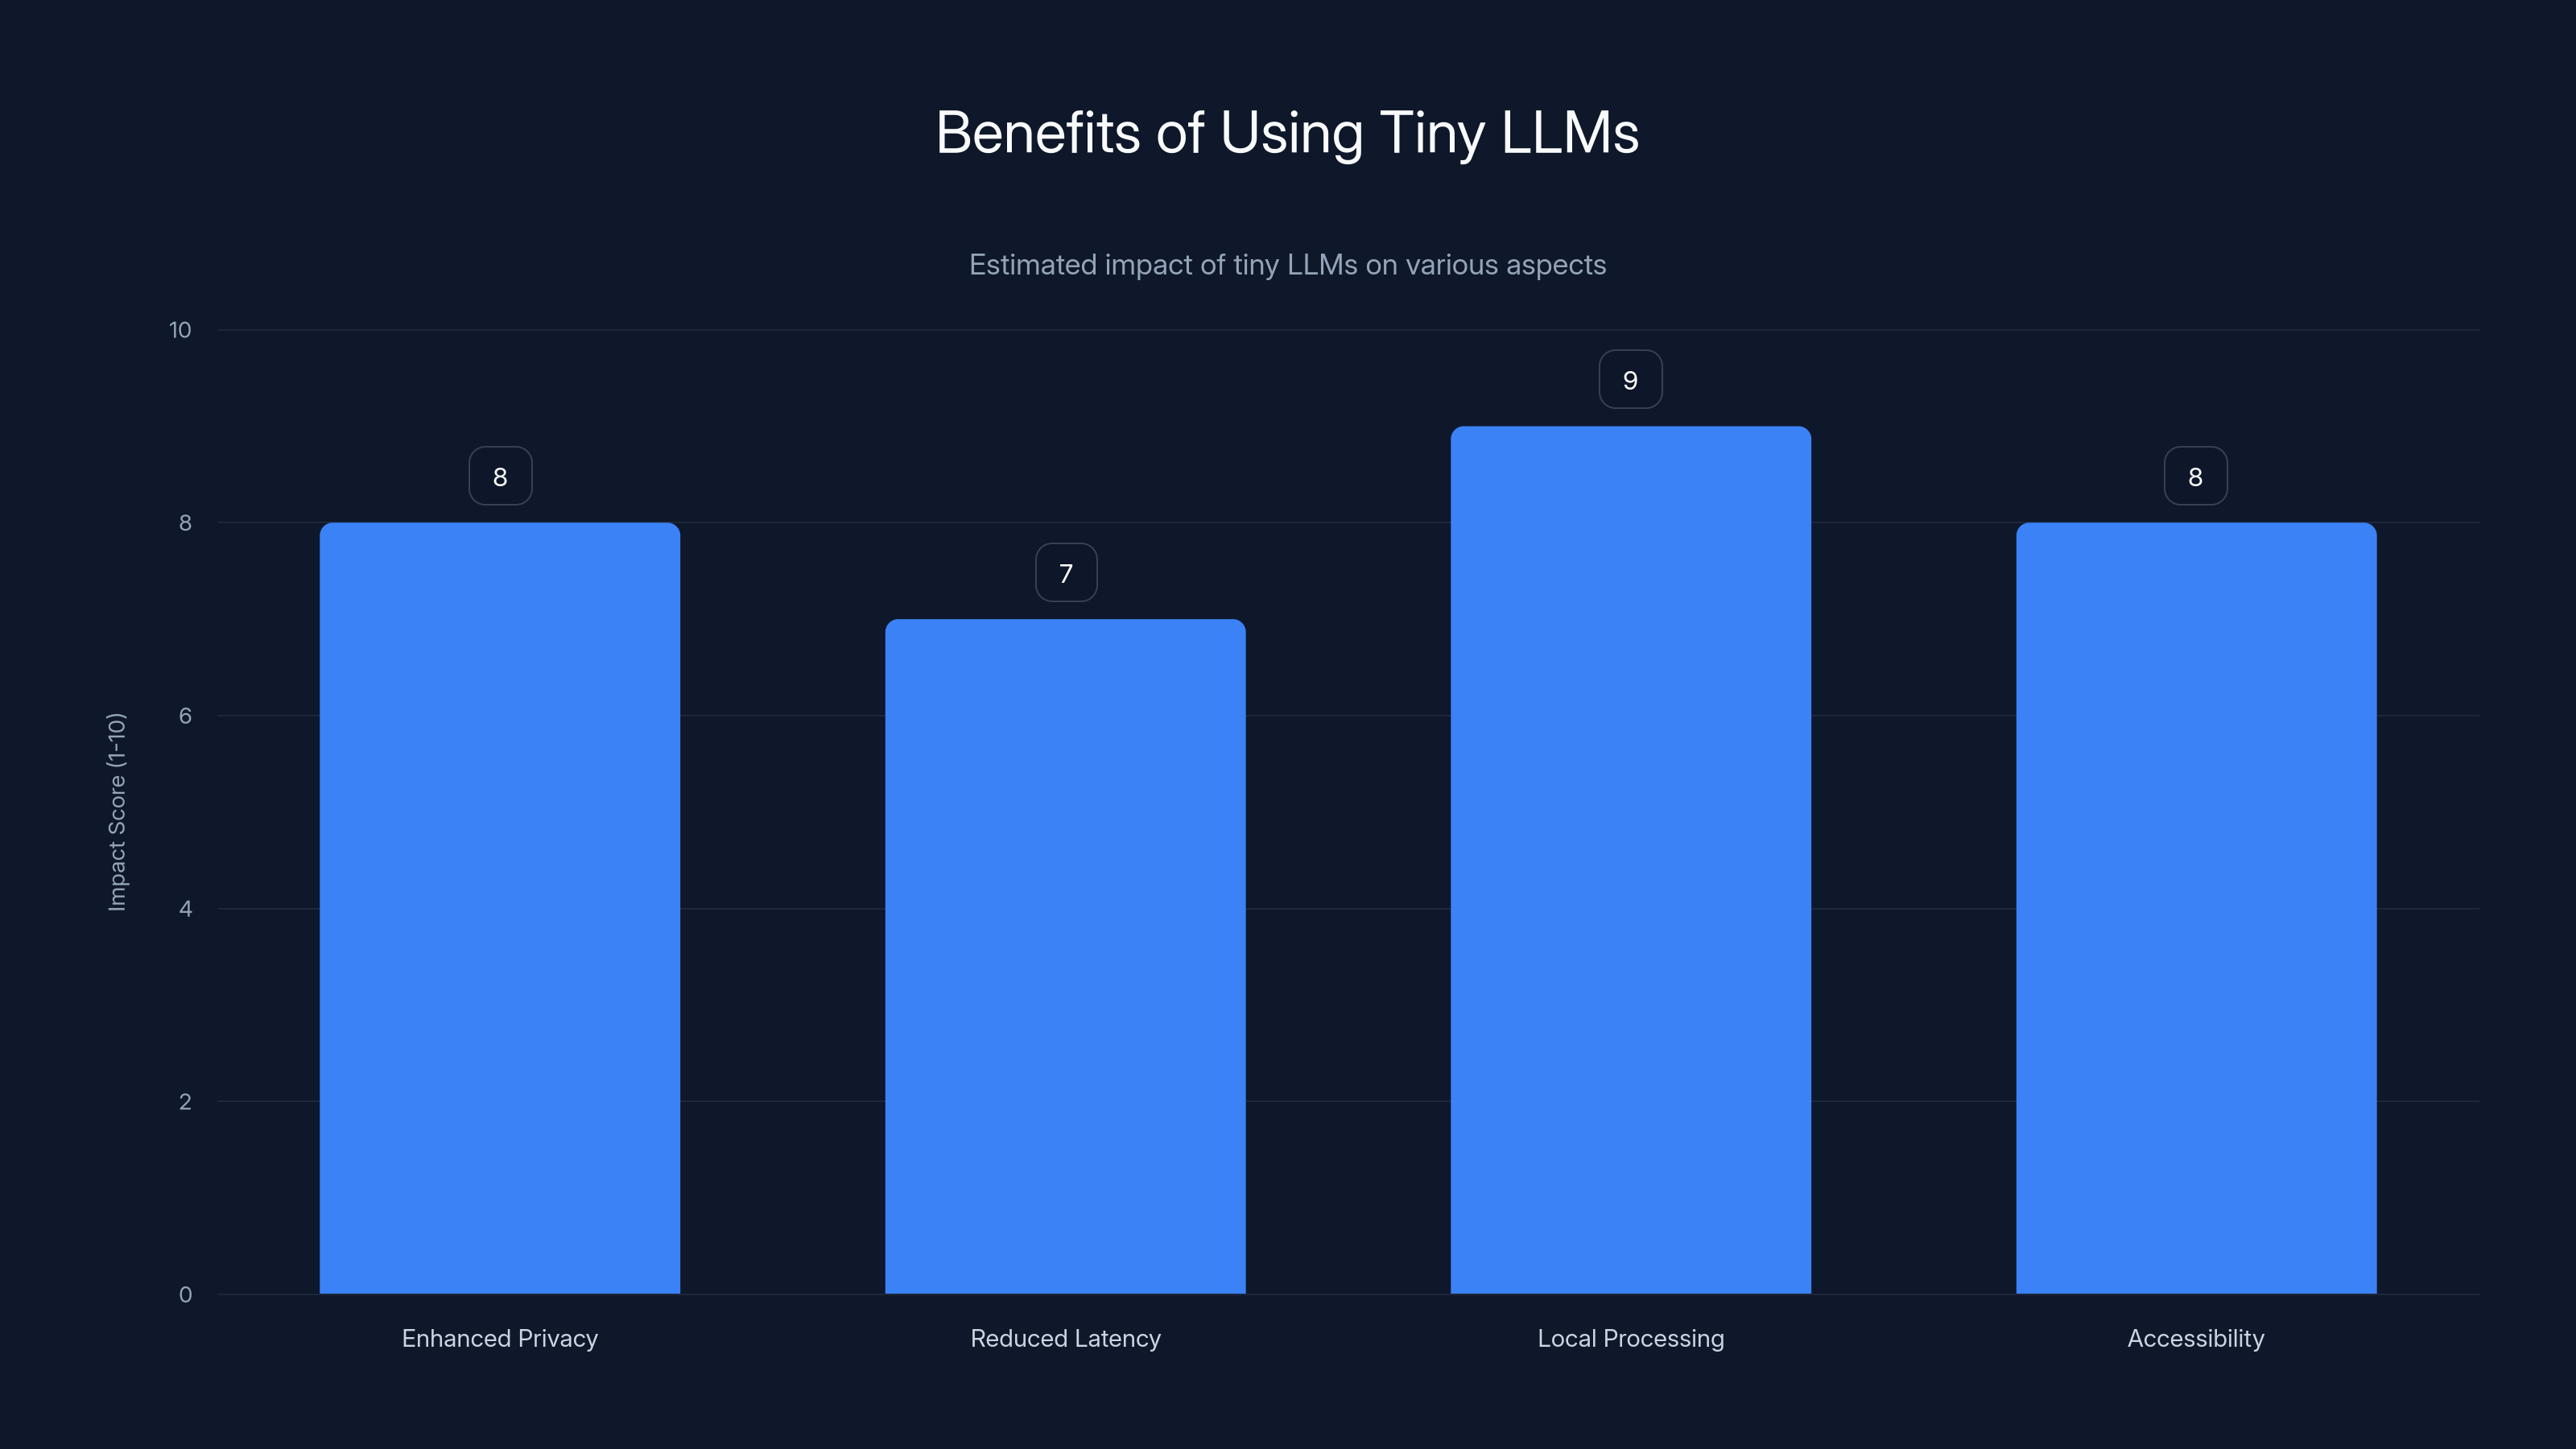
Tiny LLMs significantly enhance privacy and local processing capabilities, making AI more accessible and efficient. (Estimated data)
Introduction
In a world where AI is rapidly becoming an integral part of our daily lives, the size and accessibility of large language models have become a focal point for innovation. Prism ML is at the forefront of this transformation, offering a fresh perspective on how we can use AI more efficiently and effectively. With its latest release, the Bonsai 2 27B, Prism ML showcases the potential of small LLMs to operate on devices as common as personal computers and high-end smartphones.
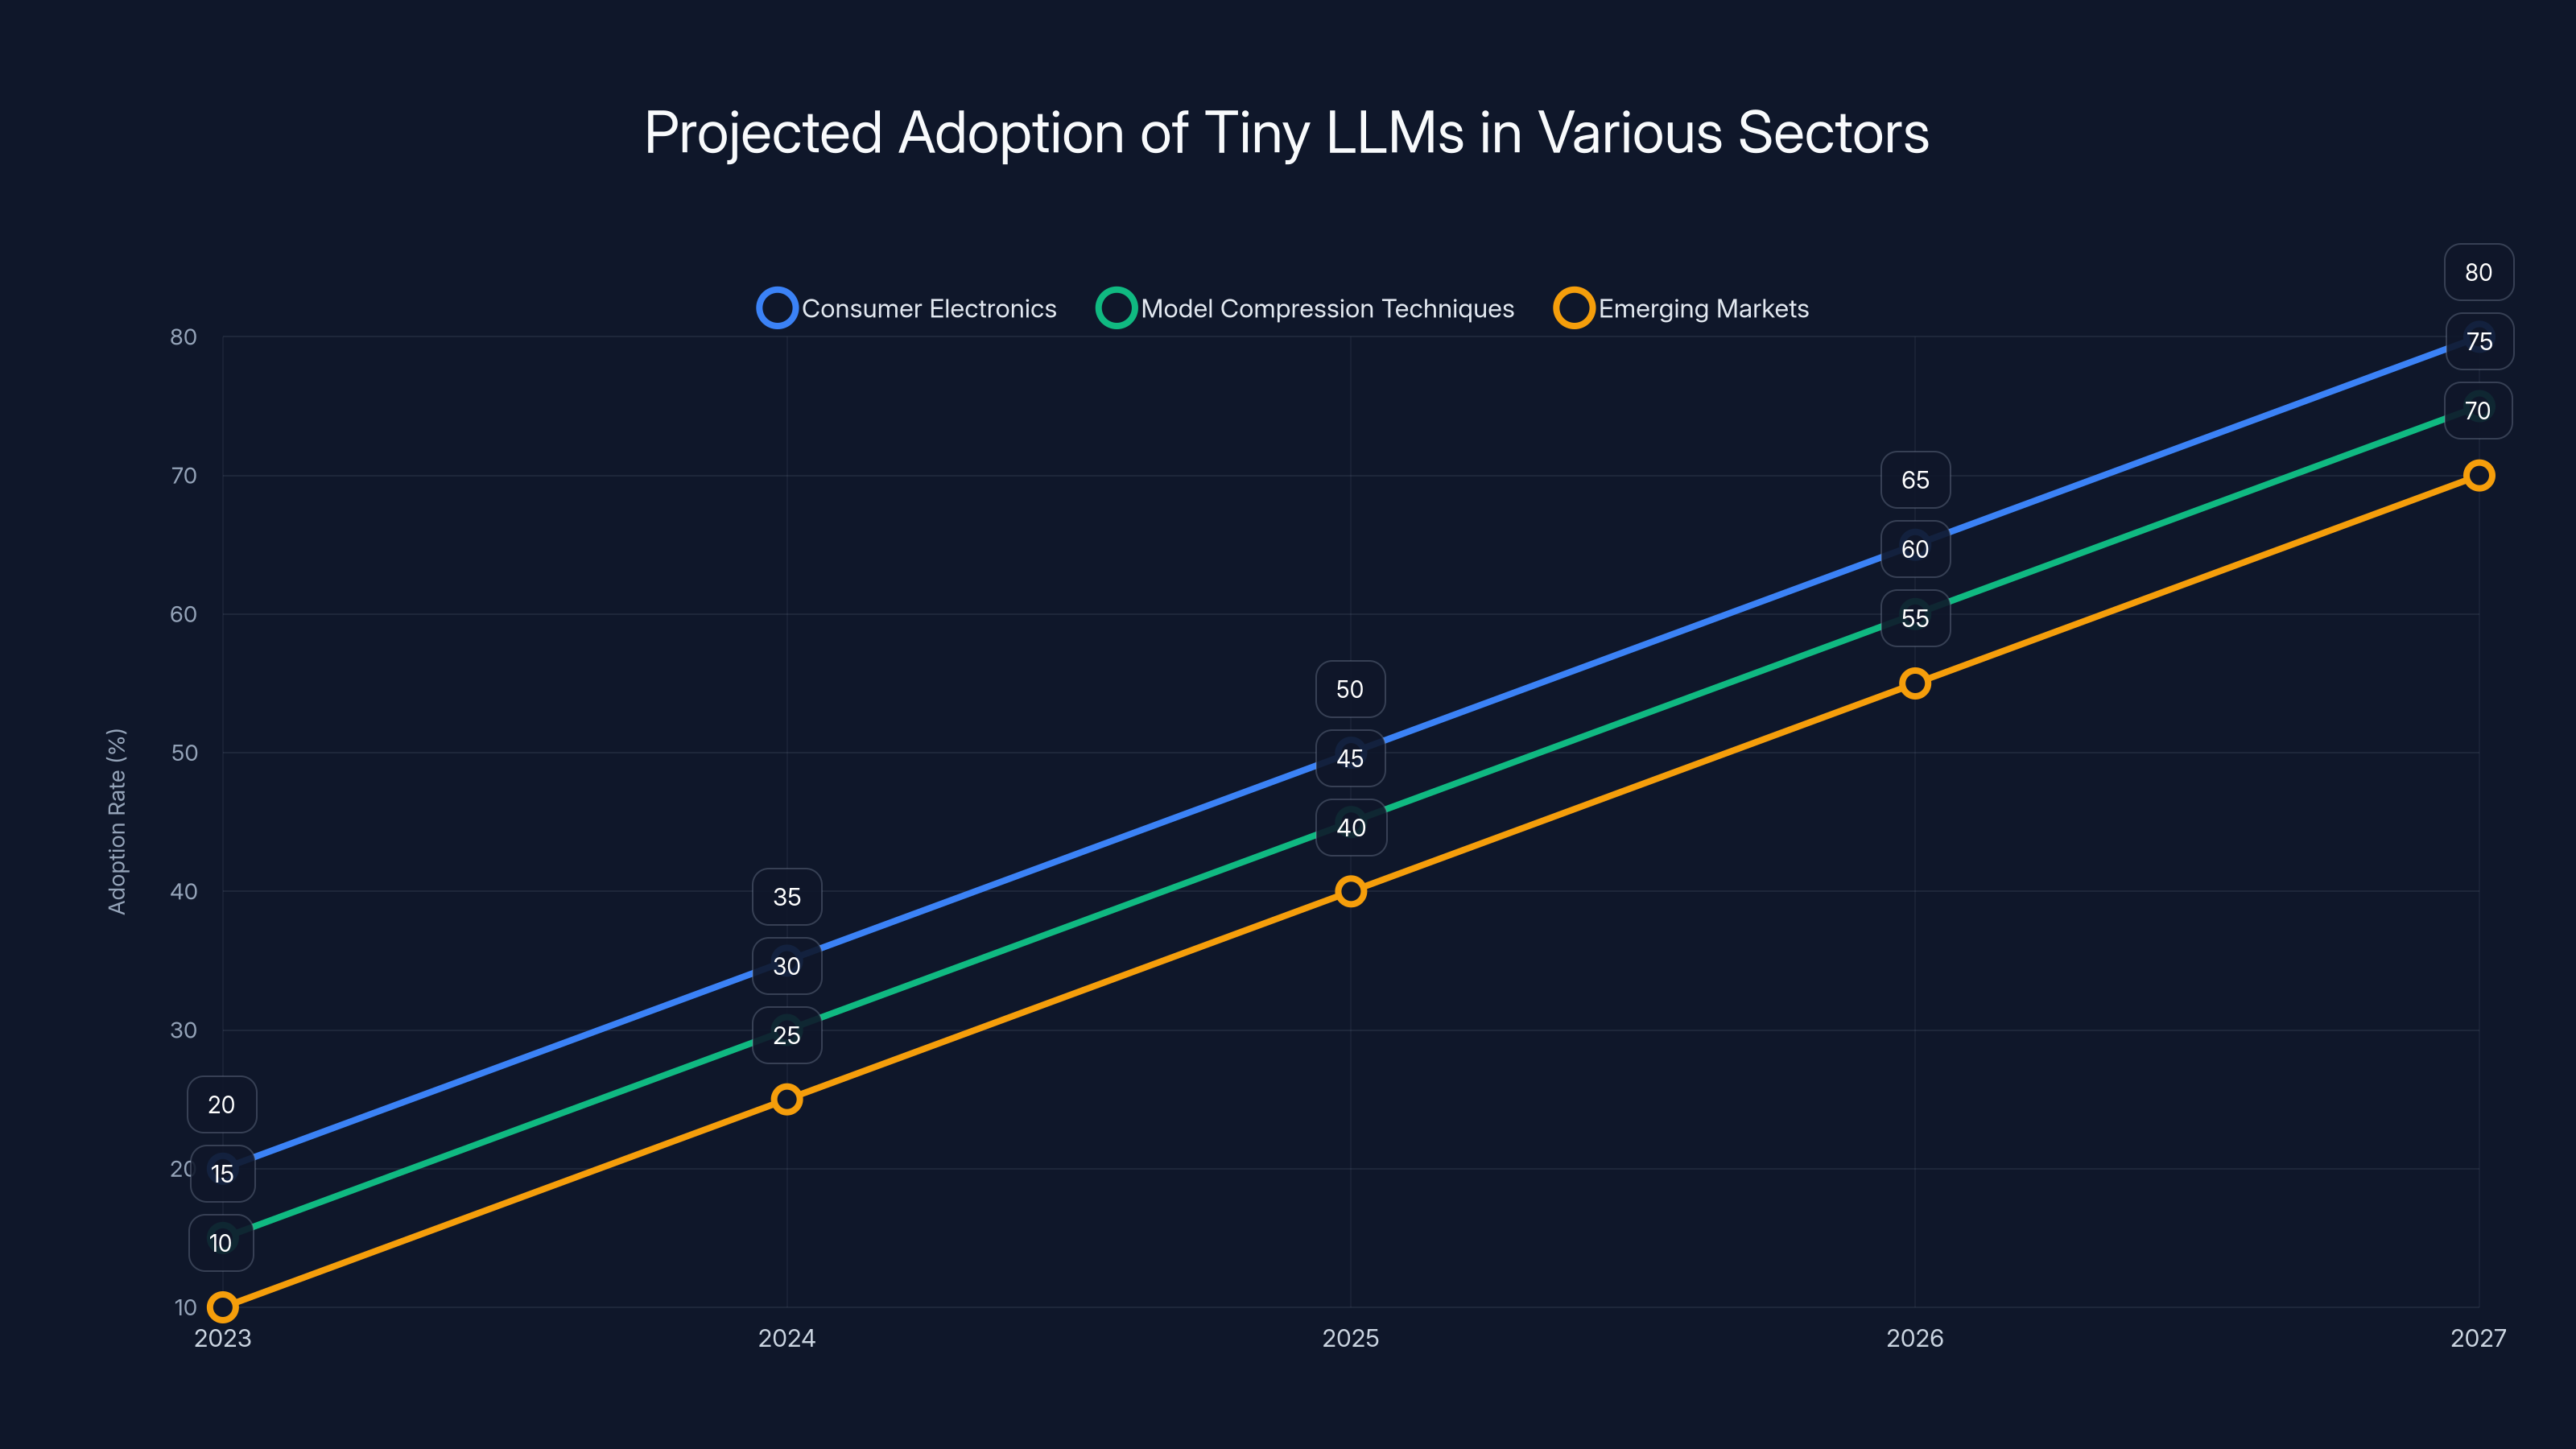
The adoption of tiny LLMs is expected to grow significantly across consumer electronics, model compression techniques, and emerging markets by 2027. (Estimated data)
The Vision Behind Prism ML
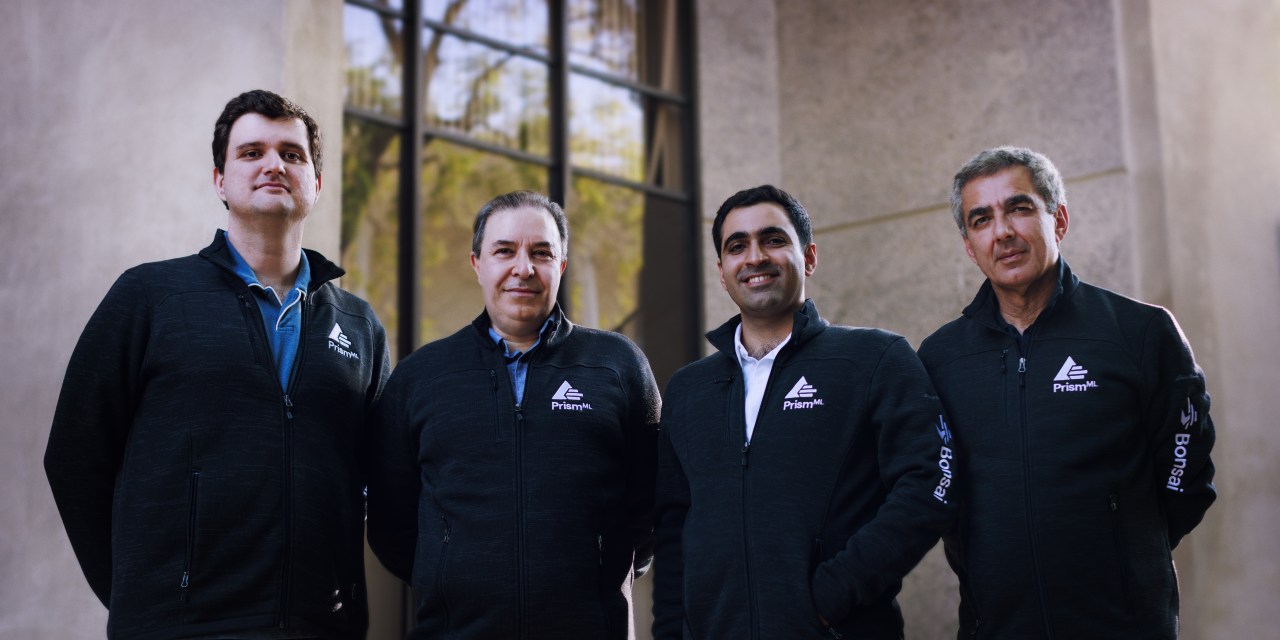
Prism ML was founded by a group of researchers from Caltech, spearheaded by Professor Babak Hassibi. Their vision is simple yet ambitious: to make high-performance AI models more accessible by drastically reducing their size. This vision is not just about making AI more portable; it's about democratizing AI, allowing more people and businesses to leverage advanced AI capabilities without the need for extensive computational resources.
Why Size Matters in AI
Large language models have traditionally been resource-intensive, requiring significant computational power and memory. This limits their deployment to powerful servers, often necessitating cloud-based solutions. However, this approach comes with drawbacks, such as latency issues and privacy concerns. By reducing the size of these models, Prism ML enables real-time, on-device AI processing, which can enhance user privacy and improve responsiveness.
Technical Innovations: The Compression Breakthrough
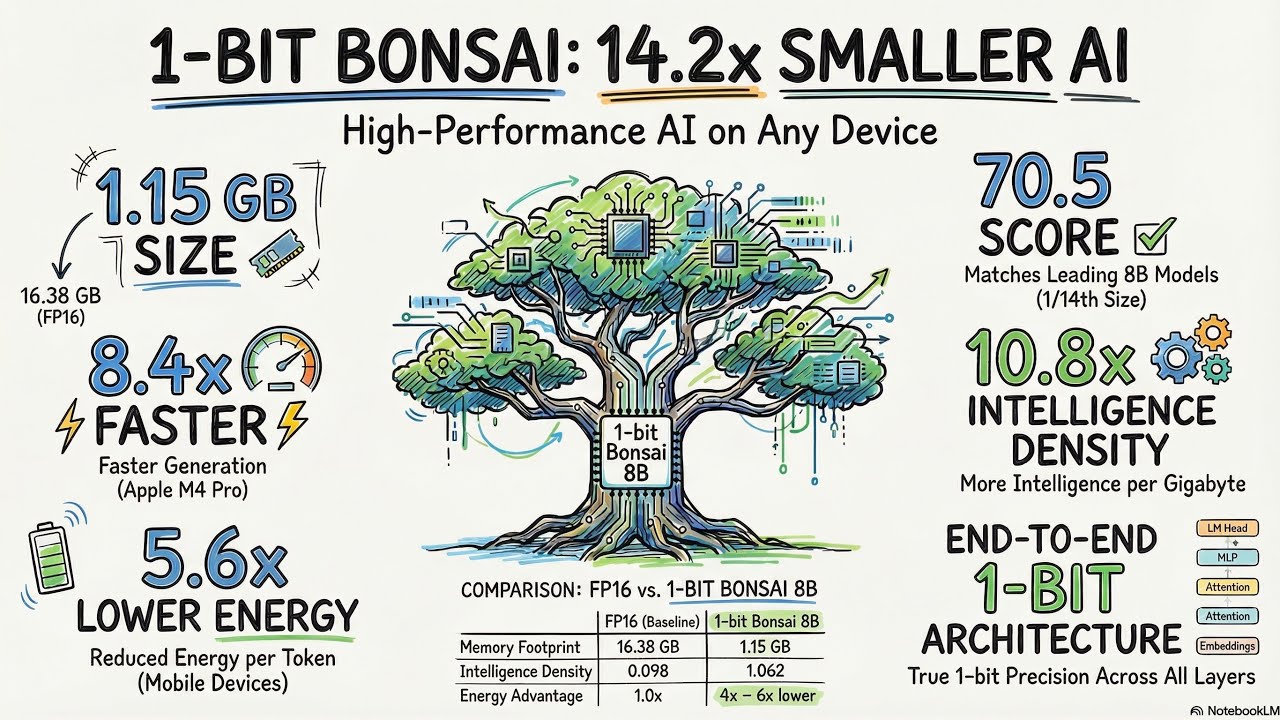
Prism ML's ability to compress the Qwen 3.8 27B model to just 5.9 GB is a testament to its advanced compression techniques. This reduction is achieved through a combination of pruning, quantization, and novel encoding strategies that retain the performance of the model while significantly decreasing its size.
Understanding Model Compression
Model compression involves reducing the number of parameters in a neural network without significantly impacting its performance. This can be achieved through various techniques:
- Pruning: Removing redundant neurons and layers that do not contribute significantly to the model's output.
- Quantization: Reducing the precision of the model's parameters, thereby decreasing the memory footprint.
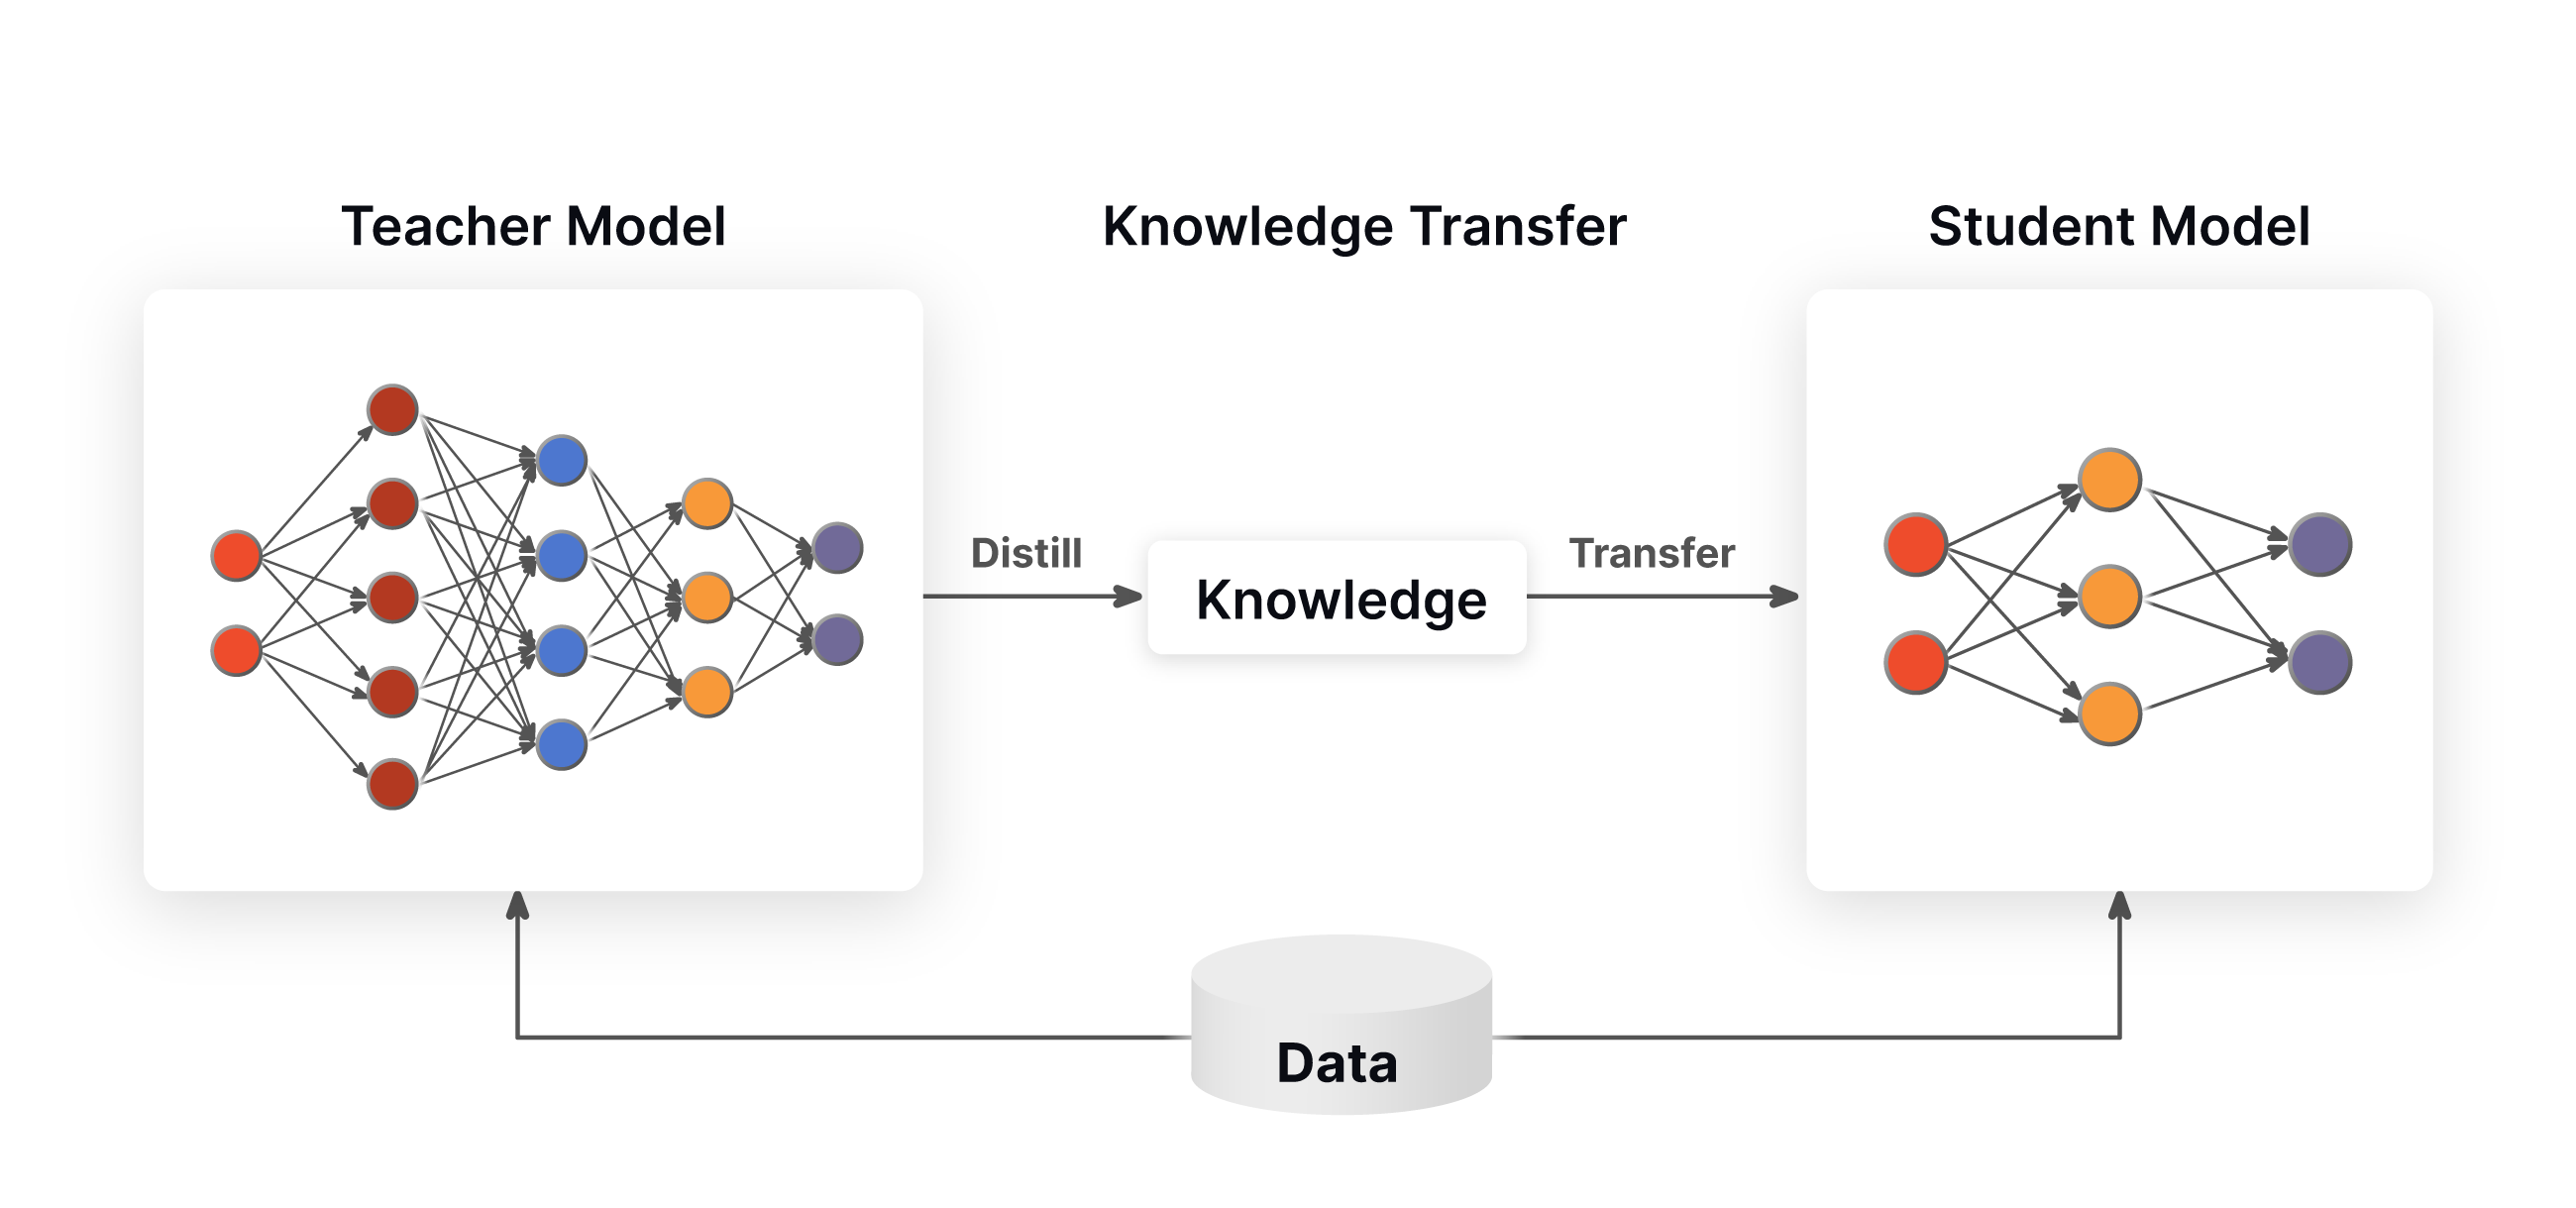
- Knowledge Distillation: Training a smaller model (student) to replicate the outputs of a larger model (teacher).
The Bonsai 2 27B: A Case Study
The Bonsai 2 27B is Prism ML's latest achievement, encapsulating the essence of their compression expertise. By employing these techniques, Prism ML has managed to maintain the model's performance while making it feasible to run on less powerful hardware.
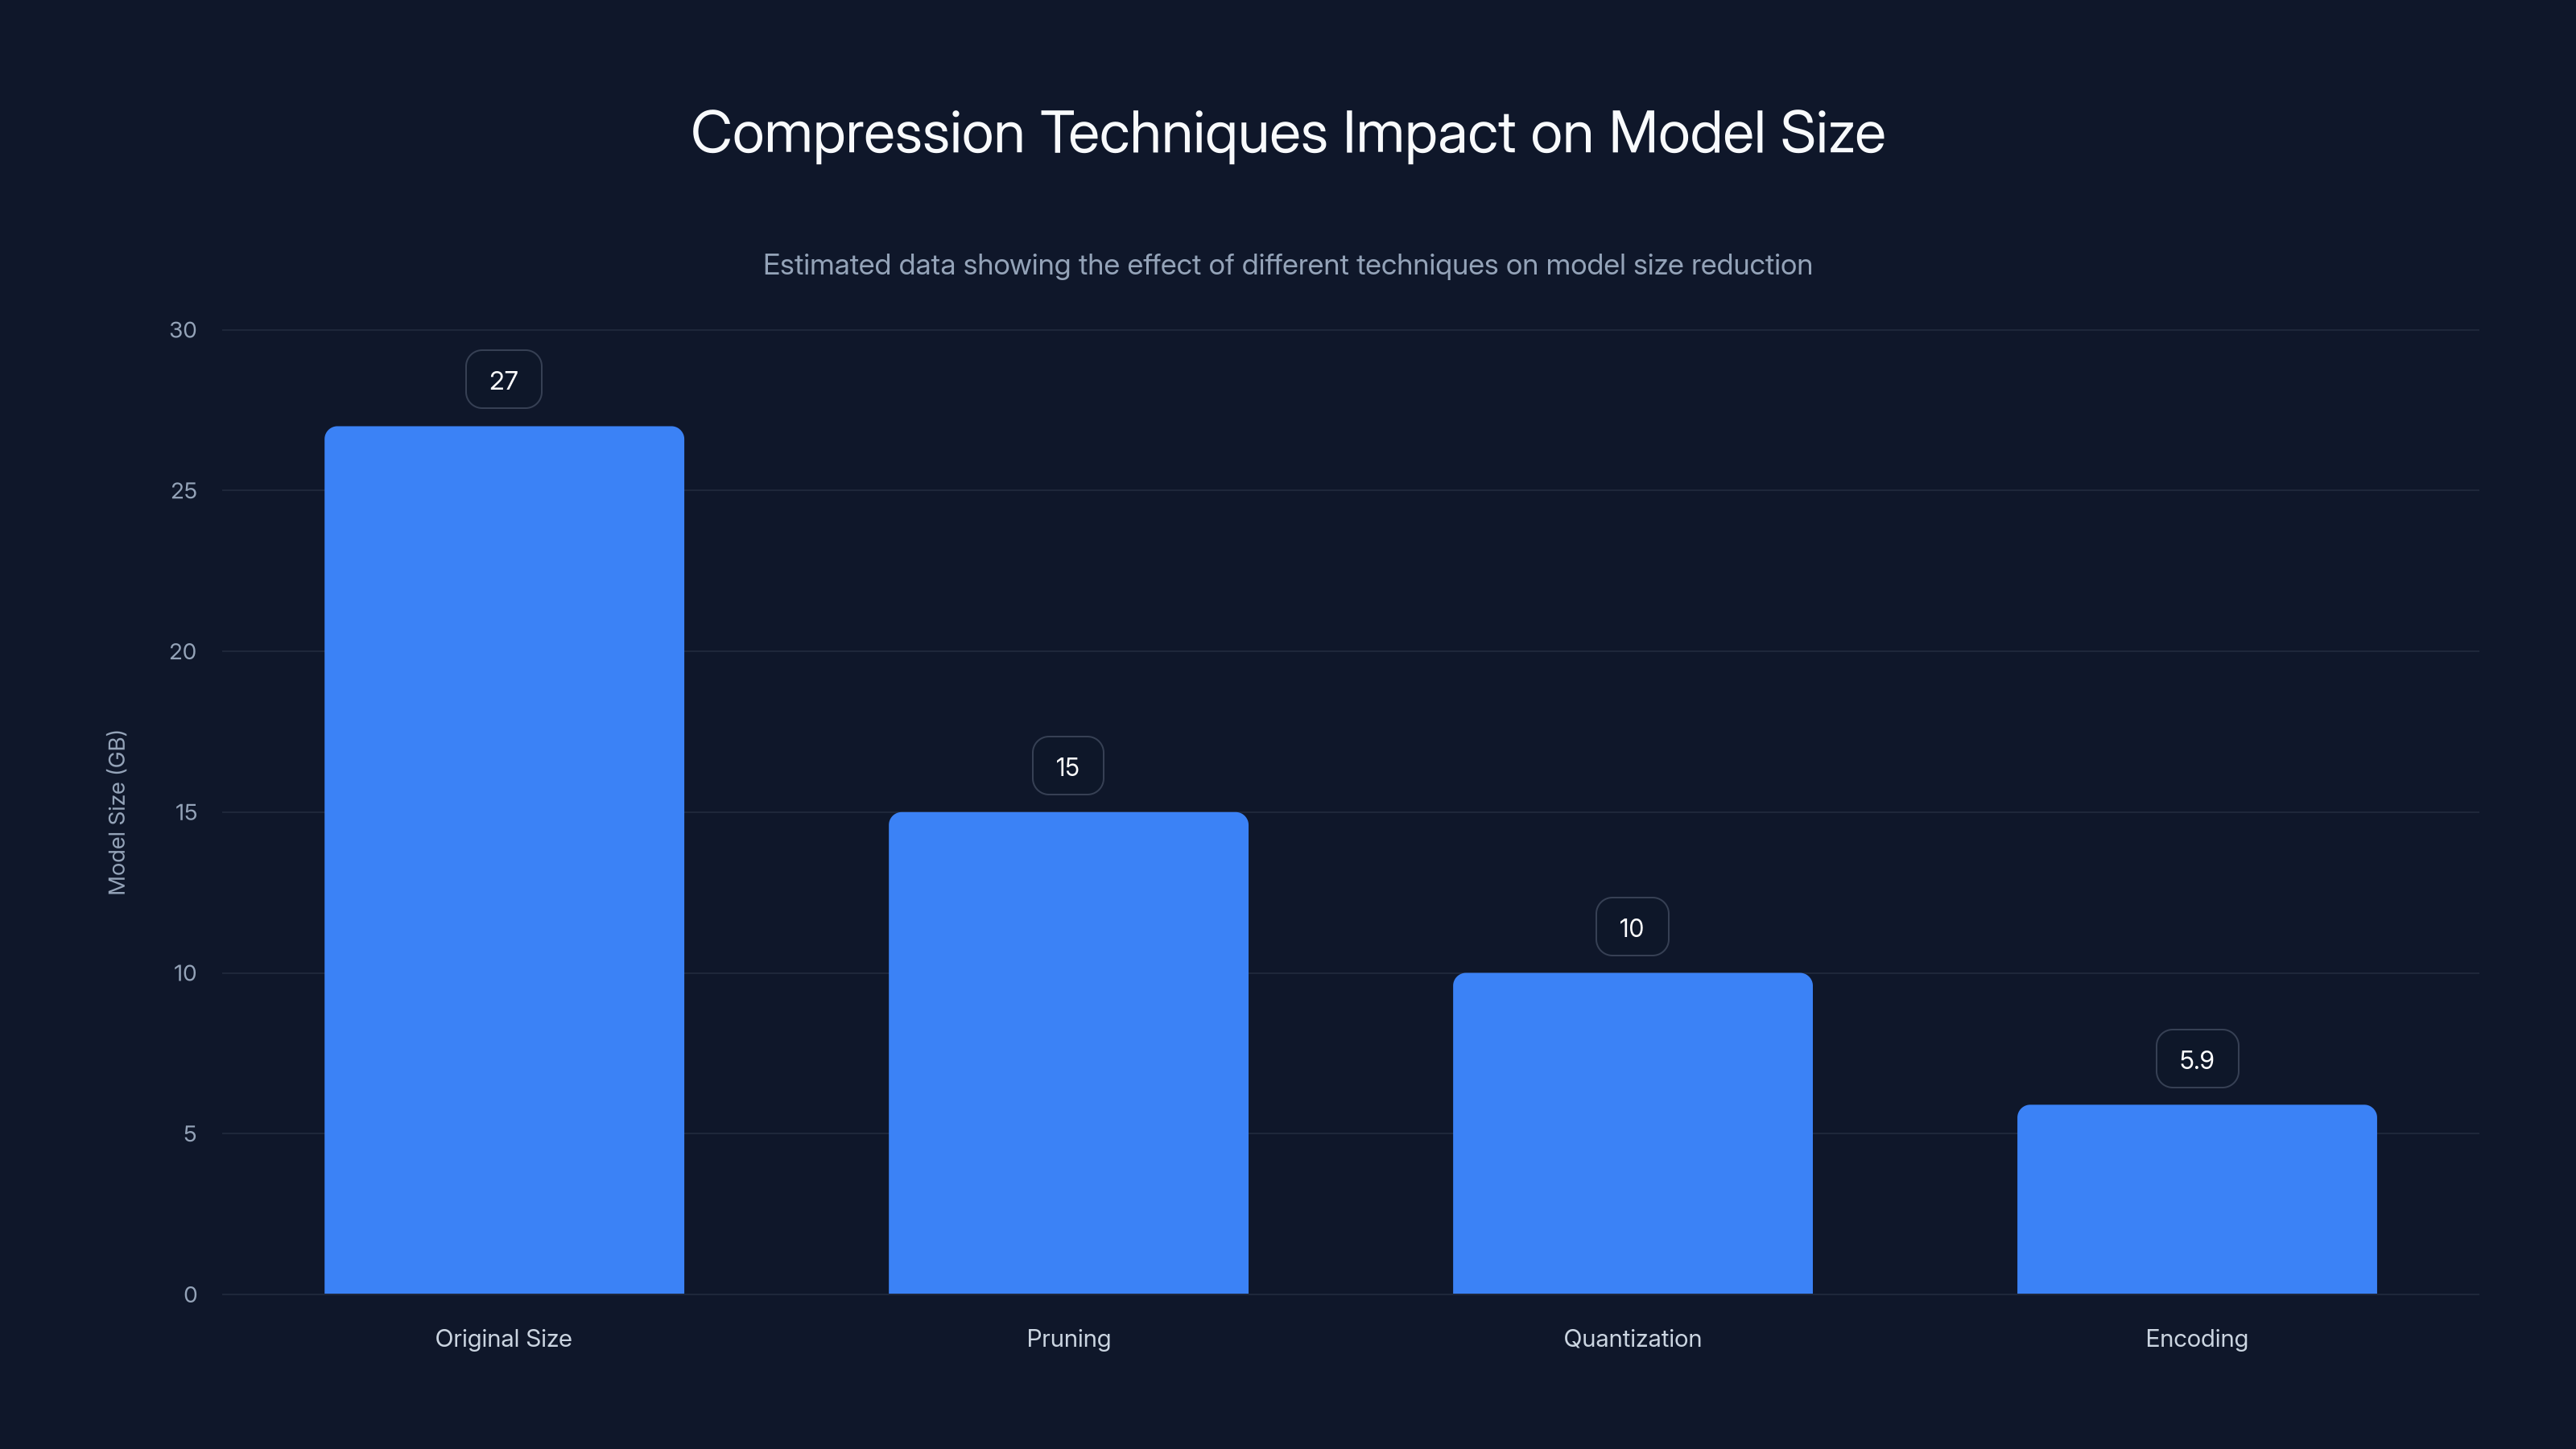
Estimated data shows how various compression techniques reduce the model size from 27 GB to 5.9 GB, with encoding achieving the most significant reduction.
Practical Applications: Where Tiny LLMs Shine
The implications of deploying tiny LLMs are vast, impacting various industries and use cases. Here are some scenarios where these models can make a significant difference:
Enhanced Mobile Applications
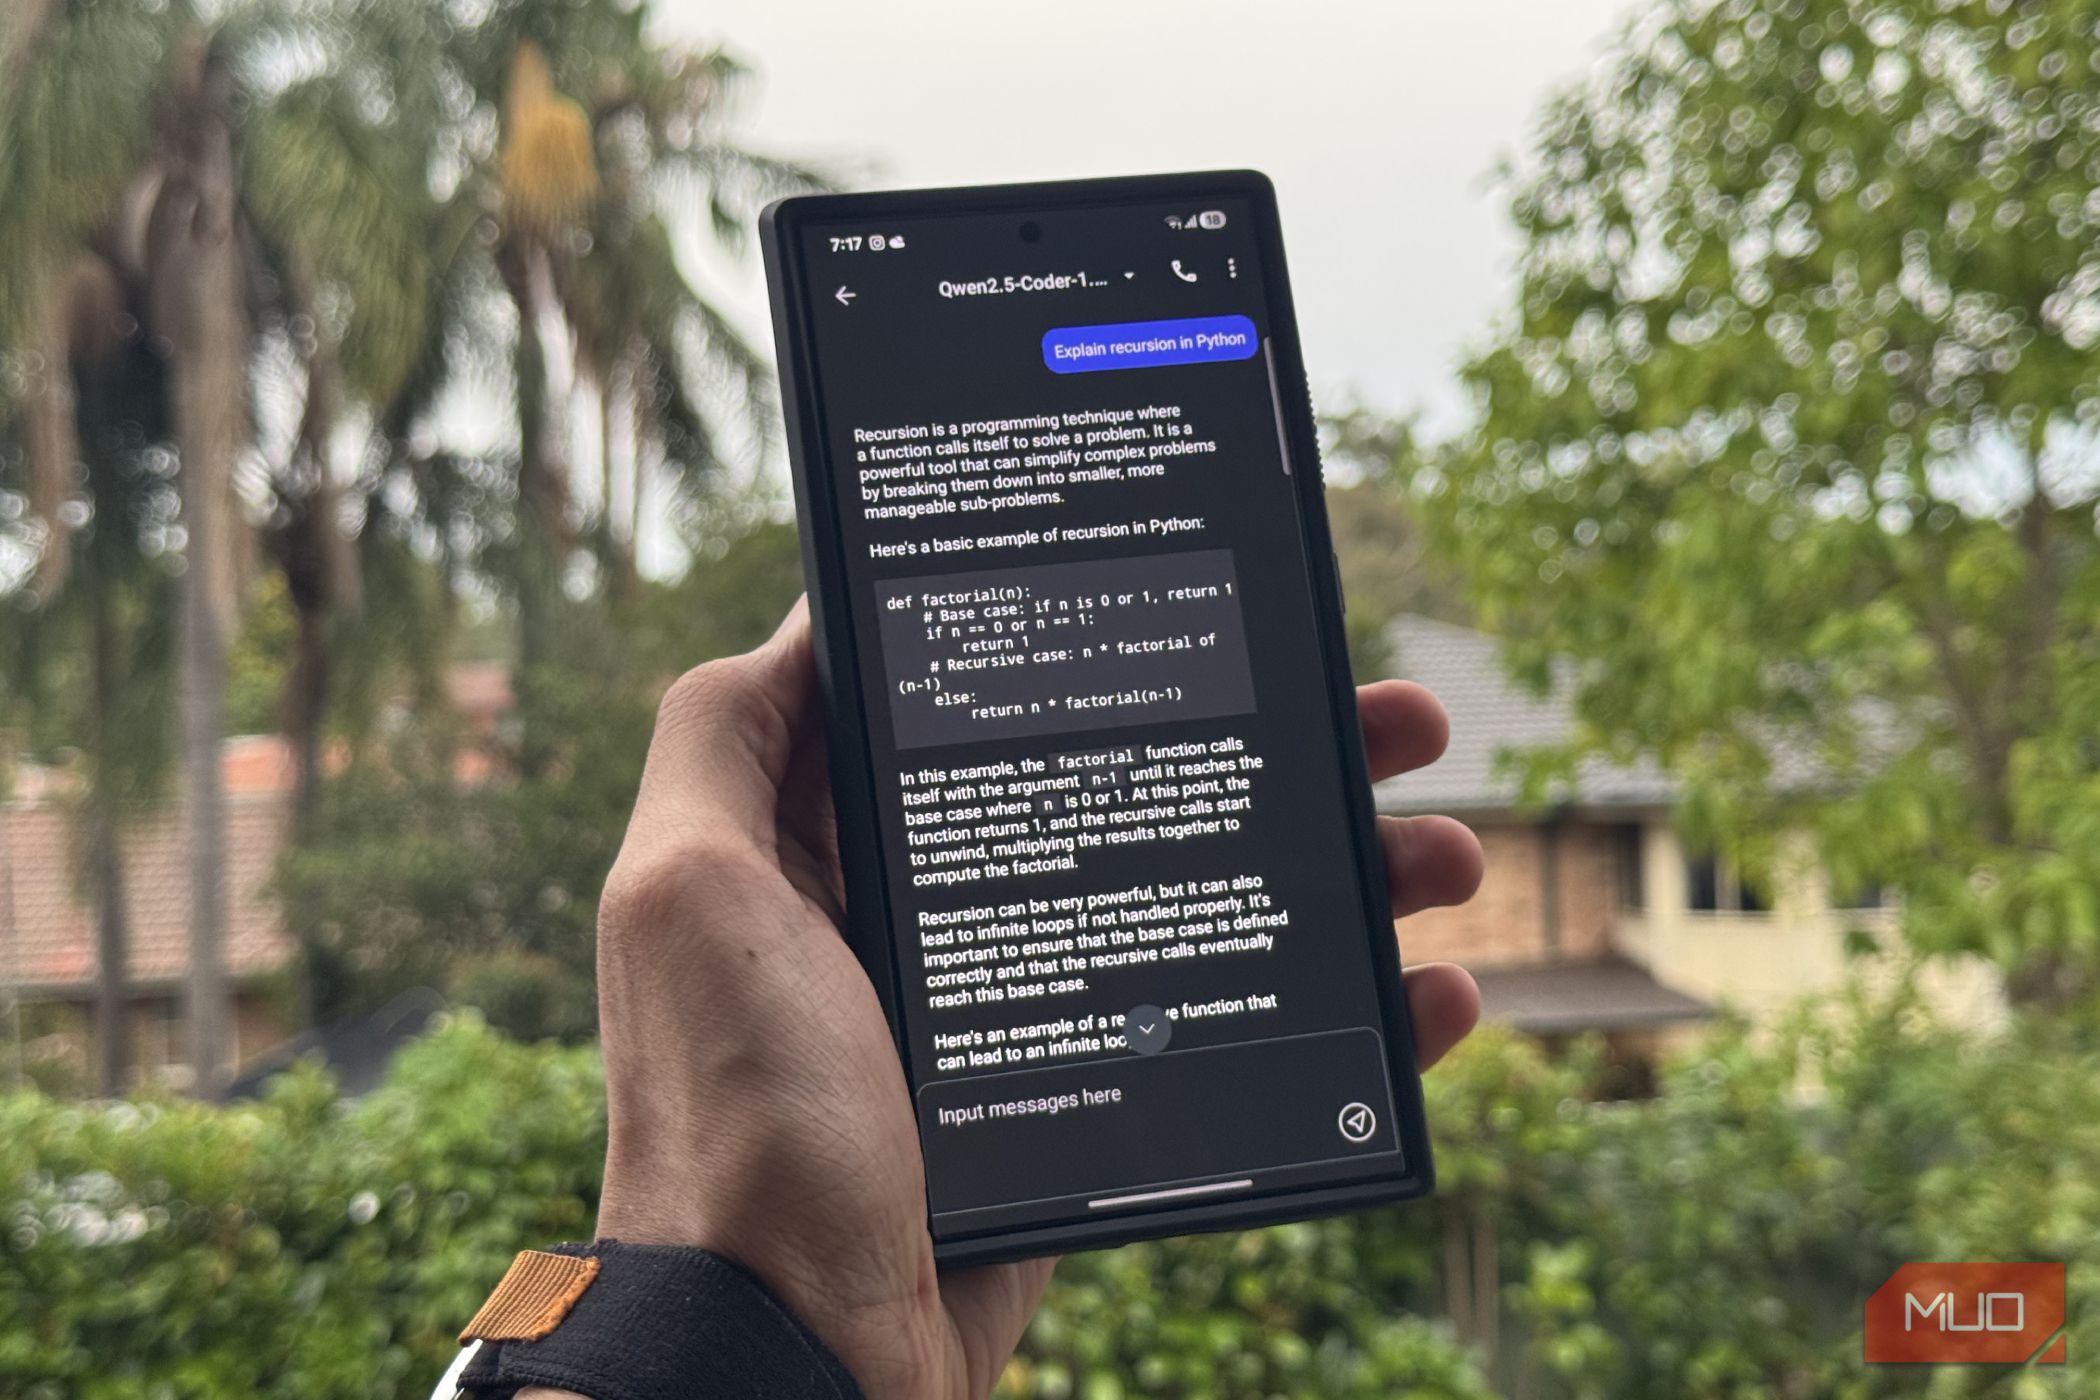
Mobile applications can leverage tiny LLMs to perform complex tasks directly on the device. This means faster response times and enhanced privacy, as data processing doesn't need to occur on external servers.
- Voice Assistants: Improved functionality with real-time processing of natural language commands.
- Image Recognition: On-device analysis, reducing the need for cloud interaction.
Io T and Edge Computing
In the realm of Io T, tiny LLMs can be deployed on edge devices, enabling local data processing. This reduces latency and bandwidth usage, making real-time decision-making possible.
- Smart Home Devices: Local processing for voice commands and environmental adjustments.
- Industrial Io T: Real-time monitoring and anomaly detection on the factory floor.
Healthcare and Personalized Medicine
In healthcare, privacy and speed are crucial. Tiny LLMs can process medical data locally, aiding in diagnostics and patient monitoring without compromising privacy.
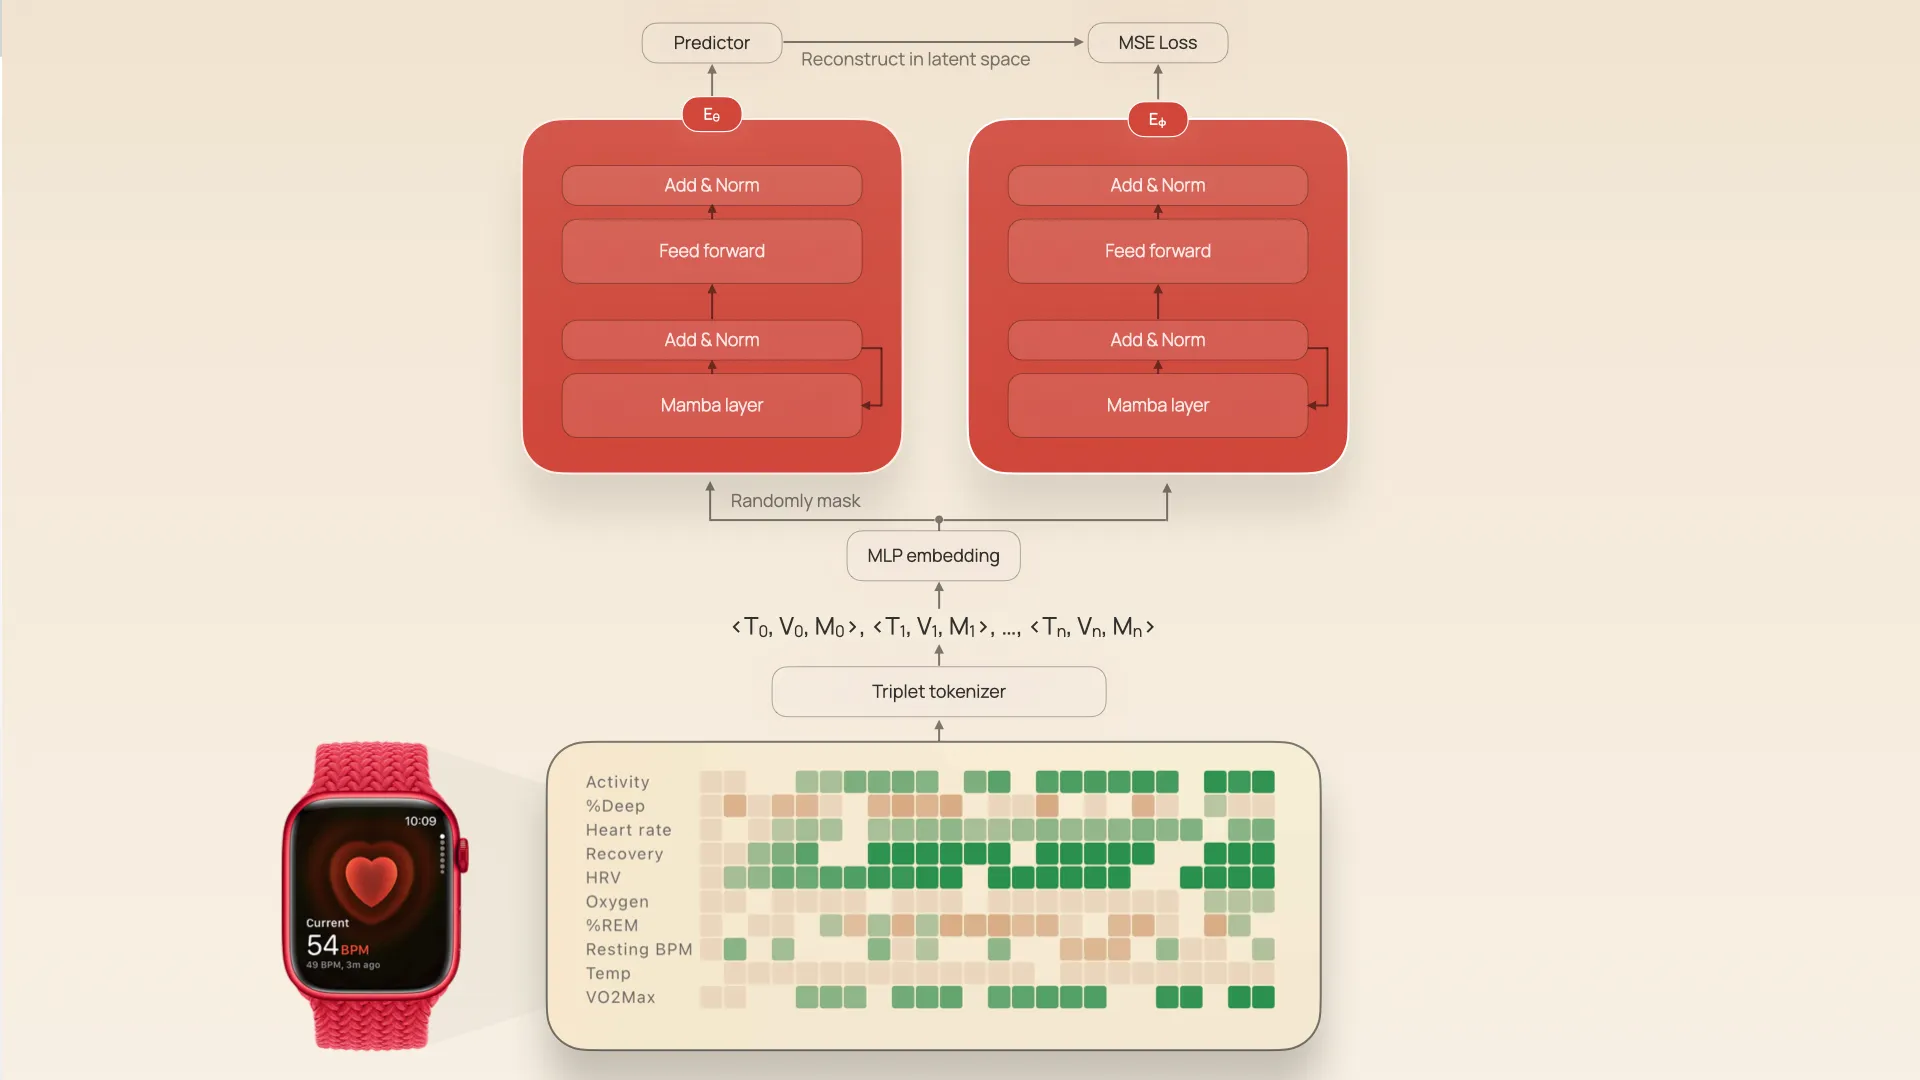
- Wearable Devices: Real-time health monitoring and alerts for users.
- Telemedicine: Enhanced diagnostic capabilities with on-device data analysis.
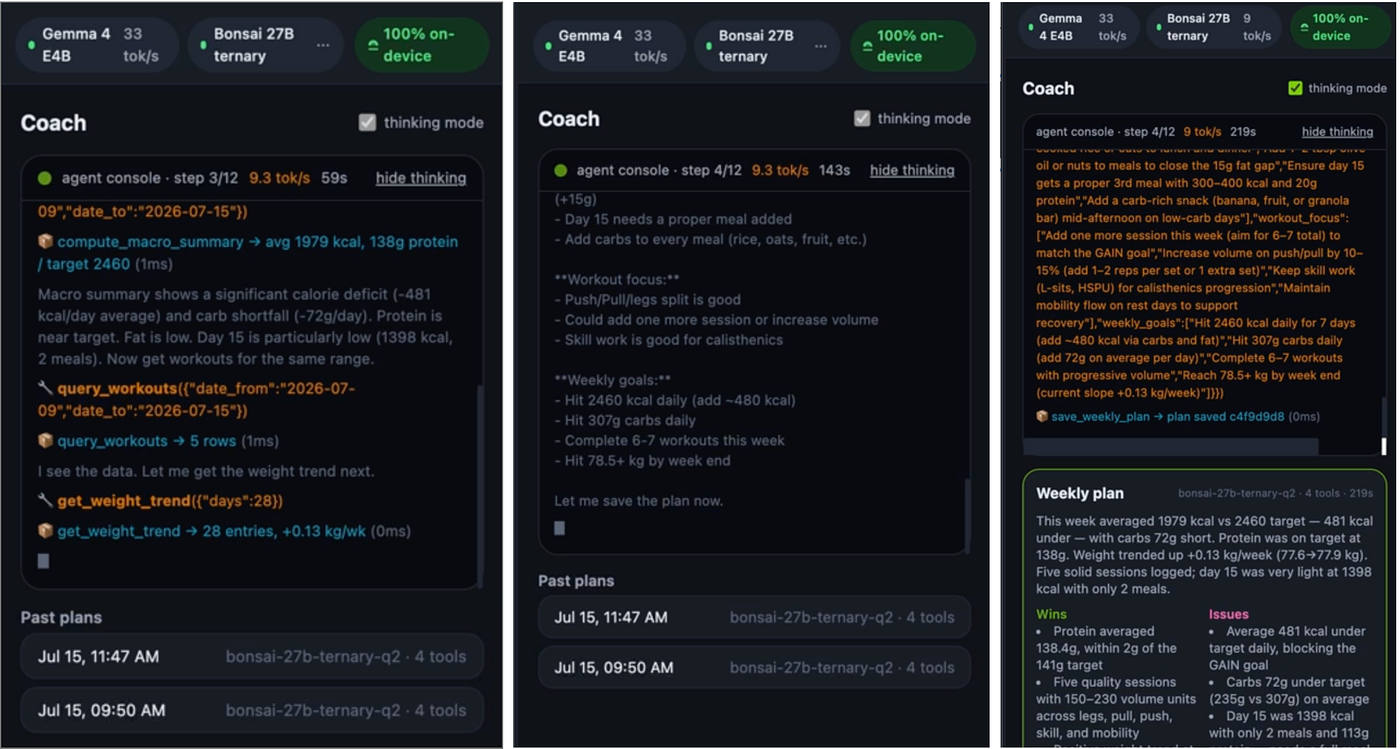
Implementing Tiny LLMs: A Developer's Guide
For developers looking to integrate tiny LLMs into their applications, understanding the implementation process is key. Here are some steps to consider:
Assessing Model Requirements
Before implementation, it's crucial to determine the specific requirements of your application:
- Performance Needs: Identify the tasks the model will perform and their computational demands.
- Hardware Constraints: Ensure the target device can support the model's size and processing needs.
Integration and Deployment
Once the model requirements are clear, the next step is integration. This involves embedding the model into the application and ensuring it functions as expected.
- API Development: Create interfaces for the model to interact with the application data.
- Testing: Perform rigorous testing to ensure the model's outputs are accurate and reliable.
Monitoring and Optimization
Post-deployment, continuous monitoring is essential to maintain model performance and make necessary adjustments.
- Performance Metrics: Track key performance indicators such as latency, accuracy, and user engagement.
- Feedback Loops: Implement systems to gather user feedback and refine the model accordingly.
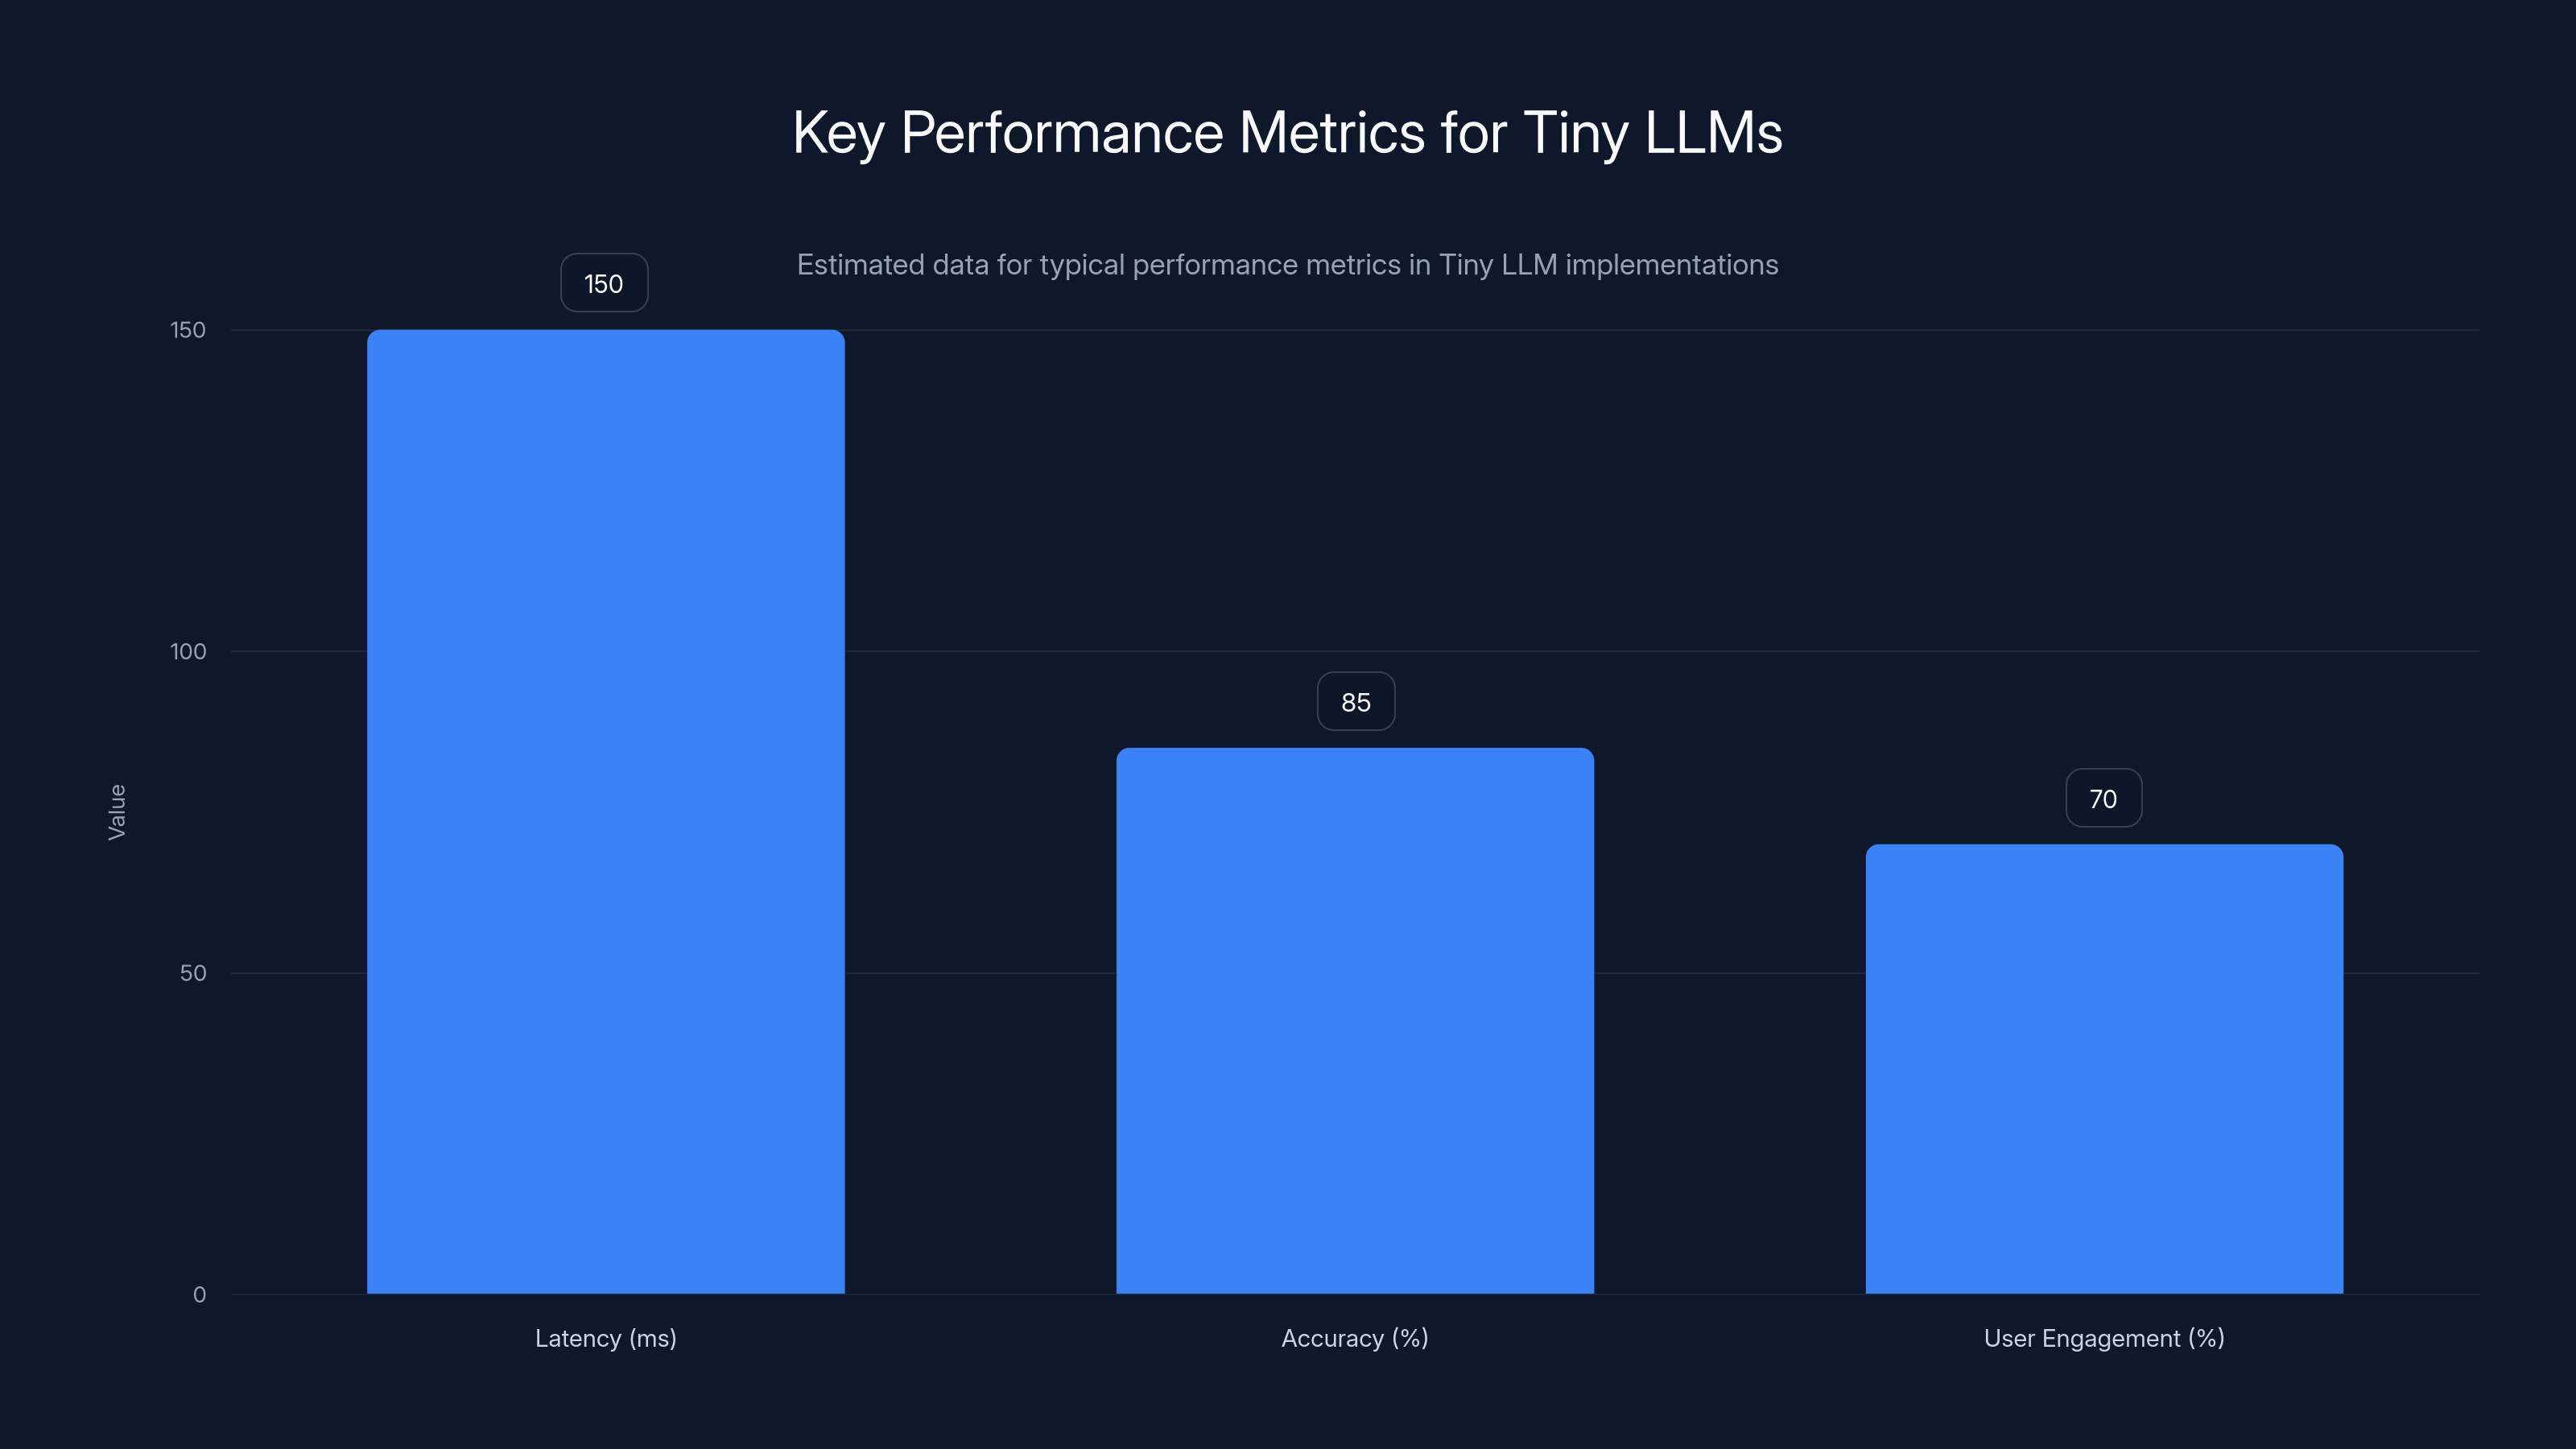
Estimated data shows typical latency, accuracy, and user engagement values for Tiny LLMs. Monitoring these metrics helps optimize performance.
Overcoming Challenges: Common Pitfalls and Solutions
While the benefits of tiny LLMs are significant, there are challenges that developers may face when implementing them:
Memory and Processing Constraints
Even with reduced size, some devices may struggle with processing power. Optimizing code and leveraging hardware acceleration can mitigate these issues.
- Solution: Use libraries designed for efficient computation, such as TensorFlow Lite or PyTorch Mobile.
Ensuring Model Accuracy
Smaller models can sometimes lead to reduced accuracy. It's essential to balance size with performance to achieve optimal results.
- Solution: Use transfer learning to fine-tune the model with specific datasets relevant to your application.
Data Privacy Concerns
With data being processed locally, ensuring user privacy is paramount. Implement robust encryption and data handling protocols to protect sensitive information.
- Solution: Adopt privacy-preserving techniques such as federated learning to minimize data exposure.
Future Trends: The Road Ahead for Tiny LLMs
The trend towards smaller, more efficient AI models is set to continue, with several exciting developments on the horizon:
Increased Adoption in Consumer Electronics
With the ability to run complex AI tasks on consumer devices, manufacturers are likely to integrate tiny LLMs into a wider range of products, from smart TVs to wearable tech.
- Trend: Expect to see AI-powered features becoming standard in everyday electronics.
Advancements in Model Compression Techniques
As research progresses, we can anticipate further innovations in model compression, making AI even more accessible.
- Trend: New techniques such as weight sharing and dynamic sparsity may lead to further reductions in model size and resource usage.
Expansion in Emerging Markets
By lowering the barrier to entry, tiny LLMs can drive AI adoption in emerging markets, where access to high-end computing resources is limited.
- Trend: More businesses in developing countries will leverage AI to improve services and operational efficiency.

Best Practices for Leveraging Tiny LLMs
To maximize the benefits of tiny LLMs, consider the following best practices:
Prioritize User Experience
Always focus on how AI integration enhances the user experience. Ensure that the AI's functionality aligns with user expectations and adds tangible value.
- Practice: Conduct user testing sessions to gather insights and iteratively improve the application.
Stay Updated with AI Trends
The field of AI is rapidly evolving. Staying informed about the latest advancements will enable you to make informed decisions about integrating new technologies.
- Practice: Follow industry publications and participate in AI-focused conferences and workshops.
Conclusion: A New Era for AI Accessibility
Prism ML's advancements in reducing the size of large language models mark a significant milestone in AI technology. By making these models more accessible and efficient, Prism ML is paving the way for a new era of AI applications that are not only powerful but also inclusive and widely applicable. Whether you're a developer, a business leader, or an AI enthusiast, understanding and leveraging these tiny LLMs can unlock new opportunities and drive innovation across various sectors.
FAQ
What is a tiny LLM?
A tiny large language model (LLM) is a highly compressed version of a traditional LLM, designed to fit on smaller devices like PCs and smartphones while maintaining performance.
How does Prism ML's compression work?
Prism ML uses techniques such as pruning, quantization, and knowledge distillation to reduce the size of LLMs without significantly impacting their performance.
What are the benefits of using tiny LLMs?
Benefits include enhanced privacy, reduced latency, and the ability to process data locally on devices, making AI more accessible and efficient.
How can developers integrate tiny LLMs into their applications?
Developers can embed these models into their apps by assessing model requirements, integrating APIs, and performing rigorous testing to ensure accuracy and performance.
What challenges might arise when using tiny LLMs?
Challenges include memory and processing constraints, ensuring model accuracy, and maintaining data privacy, all of which can be addressed with targeted solutions and best practices.
What is the future of tiny LLMs?
The future includes increased adoption in consumer electronics, advancements in compression techniques, and expanded use in emerging markets, driving innovation and accessibility in AI.
Key Takeaways
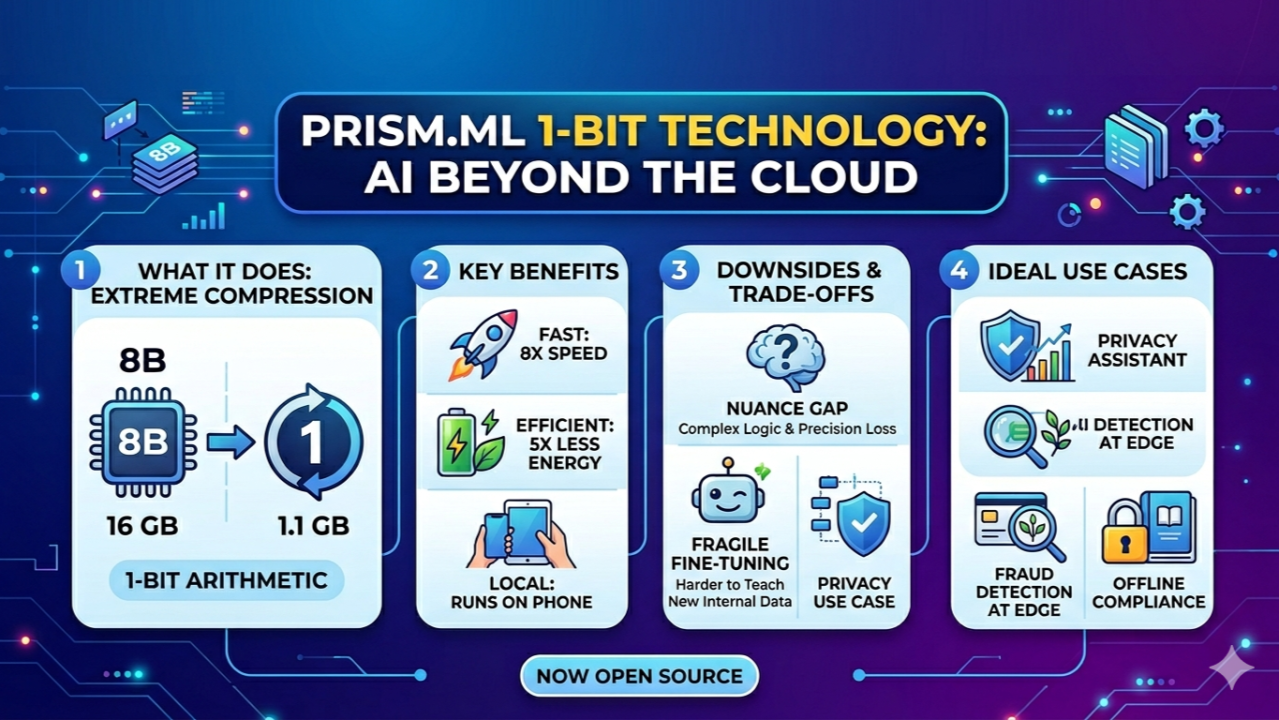
- PrismML's Bonsai 2 27B reduces model size to fit on PCs and smartphones.
- Advanced compression techniques enable real-time on-device AI processing.
- Tiny LLMs enhance privacy and reduce latency by processing data locally.
- Developers must balance model size with performance and privacy needs.
- Future trends include wider adoption in consumer electronics and emerging markets.
- Best practices involve focusing on user experience and staying updated with AI advancements.
Related Articles
- Voice AI Revolution: How Treble is Shaping the Future of Voice Simulation [2025]
- Managing Multiple AI Agents in the Cloud: Claude Code's Project Relaunch [2025]
- AI Threats and the Role of Anthropic: Insights from Microsoft's AI CEO [2025]
- Unmasking the Hidden Deceptions: OpenAI's Journey in AI Safety and Alignment [2025]
- US Cops Ignore Flock Camera Oversight: A Deep Dive into Nationwide Surveillance [2025]
- Google's New CC AI Agent: A Family's Digital Companion [2025]


